Amazon S3 Integration Connection Guide
Set up your S3 integrations to begin data discovery
Using the AWS Integration
For companies that want to find and classify files stored in S3, Transcend offers multiple integrations:
- Amazon S3 — Finds the files in your buckets and samples their contents so Transcend can classify the data in them. It sets no default file extension and no file type limit. It does not run DSR Automation actions at this time.
- S3 Parquet — Focuses on Apache Parquet format files
- S3 JSONL - Focuses on JSON and JSON Lines format files
Connecting the Integration
Similarly to the AWS integration, S3 integrations are scoped to a single AWS account. If you have multiple AWS accounts to connect, you must add a data system for each account.
1. Add the Integration
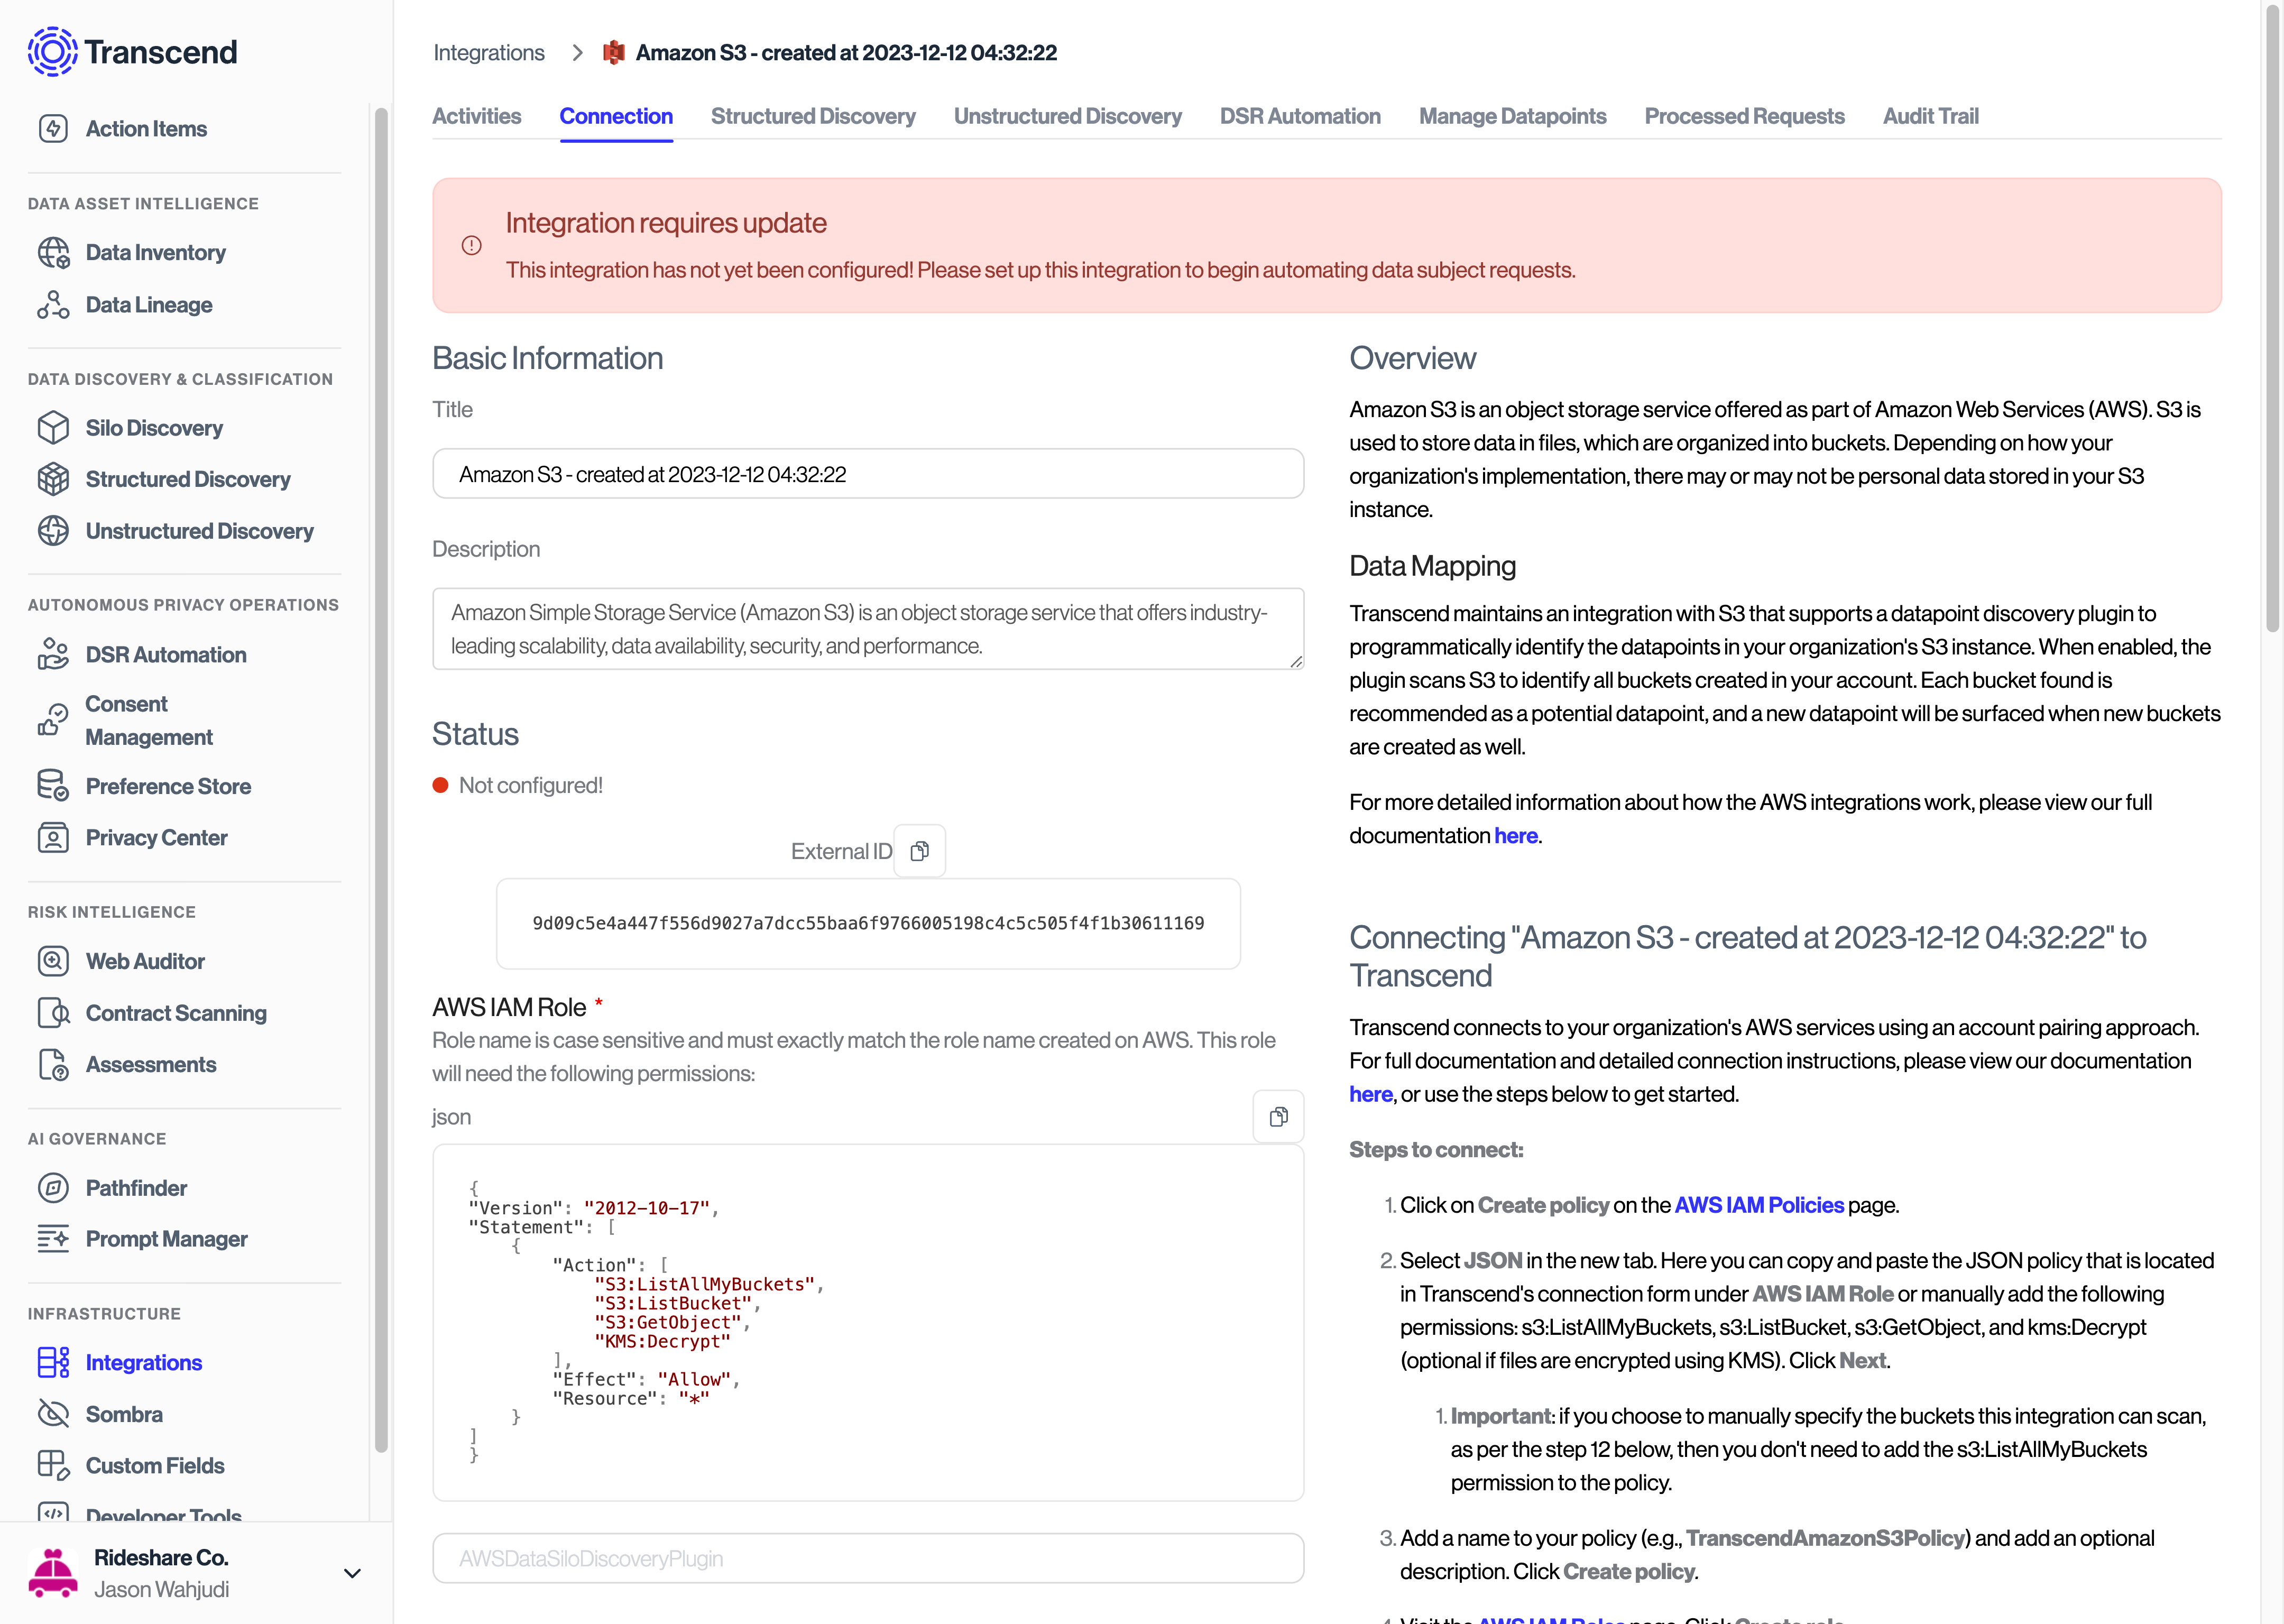
- You must first add the integration to your Transcend account and visit the connection form. Here is an example using the Amazon S3 Integration
2. Create a new Role in the AWS IAM Console
- In
Select trusted entity, select AWS account as the trusted entity type. Here you will put:- For Multi-tenant Sombra, include 829095311197 (Transcend's Account ID).
- For Self-hosted Sombra, include the account ID of where the self-hosted Sombra is hosted in
- Select
Require external IDand copy/paste the External ID provided on our integration connection page (see below).
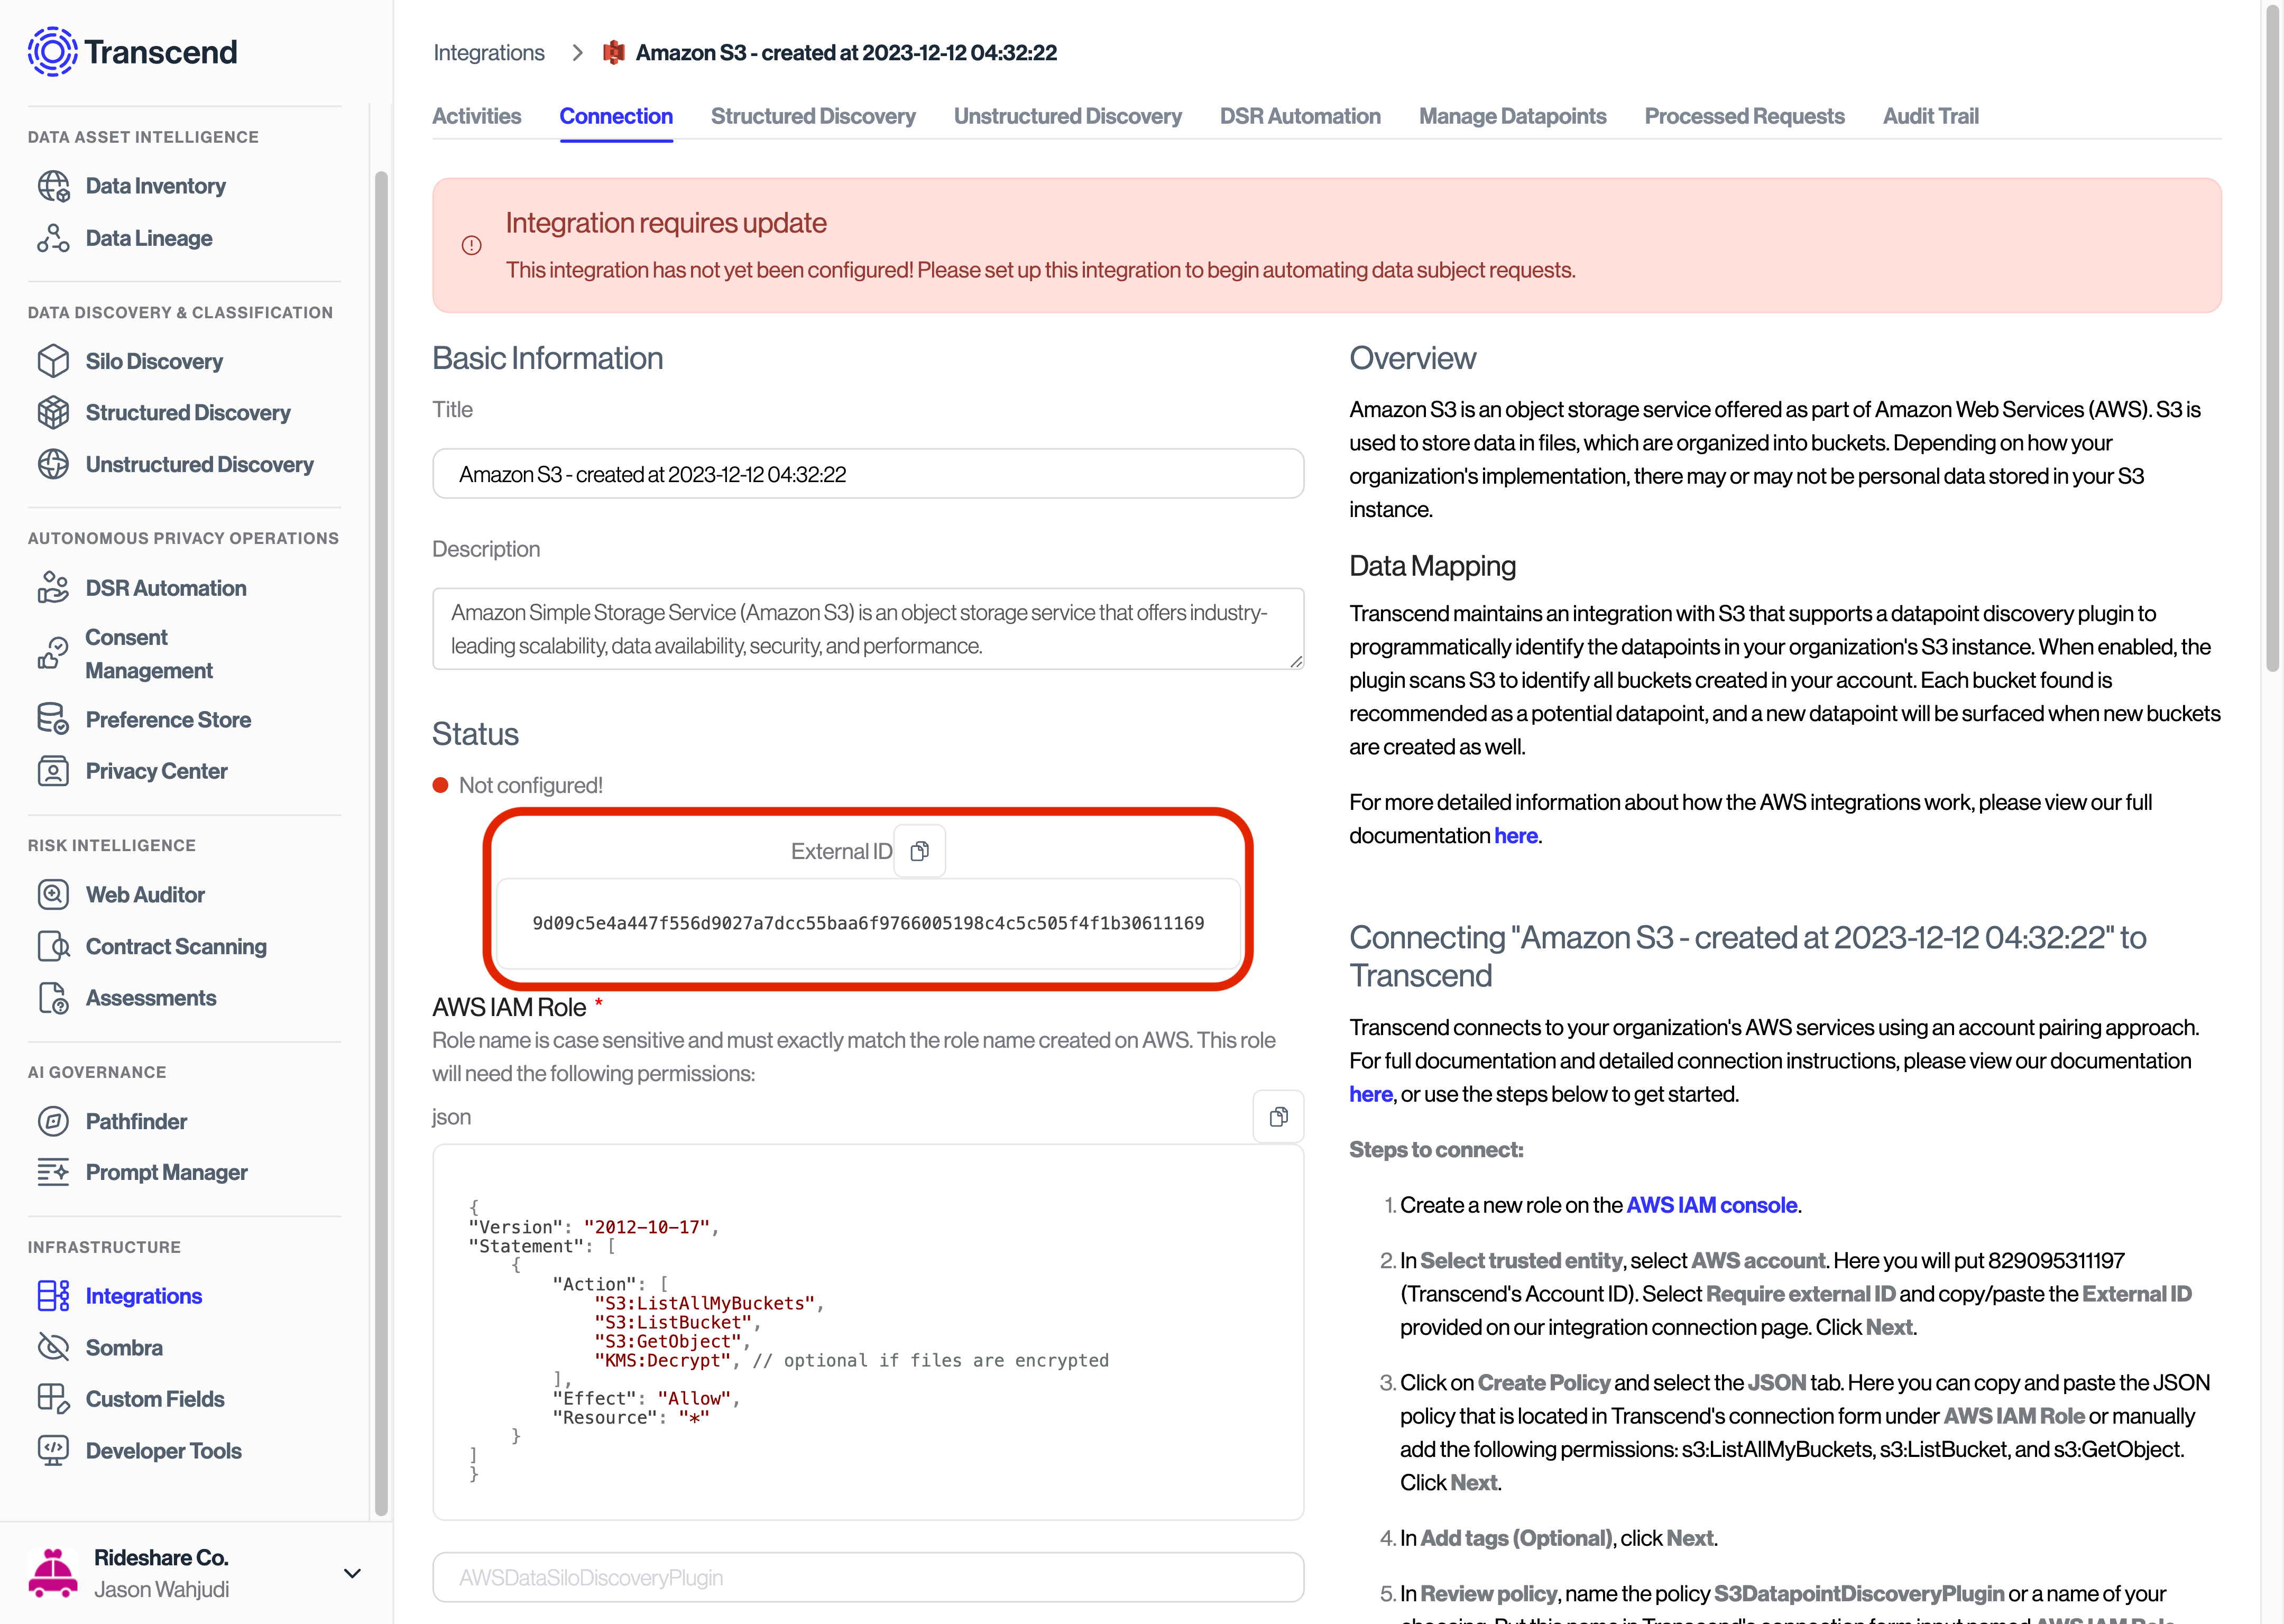
- Click Next.
- Once the role is created, you can navigate to the Trust Relationships tab of the role and the trusted entity should generally look something like this:
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": {
        "AWS": [
          "arn:aws:iam::<transcend-or-self-hosted-sombra-account-id>:root"
        ]
      },
      "Action": "sts:AssumeRole",
      "Condition": {
        "StringEquals": {
          "sts:ExternalId": "5ab4defb0bef8e2bf4b9e636c3949f3edff73c5fb2eb0f56d84a913bd38b8445"
        }
      }
    }
  ]
}
3. [Self-hosted Sombra] Ensuring Sombra Cluster can Assume the Created Role
- For self-hosted Sombra, make sure that the Sombra cluster has the permission to also assume the role.
- If you host Sombra via our Terraform Module, you may add this by updating the roles_to_assume variable.
- Otherwise, adjust the IAM permissions attached to the Sombra cluster to have
sts:AssumeRolepermissions on the IAM Role you created.- If your Sombra cluster is hosted on an ECS cluster, you would also need to include the role attached to that cluster as well
- The policy should generally look something like this:
{
  "Action": ["sts:AssumeRole"],
  "Resource": [
    "arn:aws:iam::<sombra-account-where-role-lives>:role/<name-of-role>",
    "<any other resources ...>"
  ],
  "Effect": "Allow"
}
4. Define the Permissions for the Role
- Either create or pick a policy containing the
s3:ListBucketands3:GetObjectpolicies. The former allows us to read the files from within your buckets. The latter lets us read the files themselves. - If your files are encrypted using KMS, also include the
kms:Decryptpolicy to allow us to decrypt the object. - If you want Transcend to scan all of your buckets in S3, you must also add the
s3:ListAllMyBucketspermission. Otherwise, you can manually enter the bucket names in the Buckets fields. For more info, see step 6 below.- Note that this call would grab all buckets from all regions. We recommend that if there are buckets living in different regions, to make a new S3 integration specific for each region.
5. Name, Review, and Create the Role
- In the next page, pick a name for your Role (e.g., TranscendS3Role) and add a description.
- Review the selected trusted entities and permissions, and create the role.
6. Fill out the Connection Form
- Head back to the connection form in the Admin Dashboard.
- Add the name of the created role, as well as your AWS Account ID and region.
- Buckets is optional. Enter a comma-separated list of one or more buckets. If you leave it empty, Transcend scans all buckets that the role can list.
- If you didn't add
s3:ListAllMyBucketsin step 4 above, list your buckets. - On the Amazon S3 integration, this field applies to System Discovery only. To limit the buckets for Unstructured Data Discovery, set Buckets in the plugin settings on the Scan Configuration tab. See Amazon S3 Plugins Configuration.
- If you didn't add
Scan filters
For S3 Parquet and S3 JSONL, the connection form also has these filters. They help you run scans that fit your needs.
- Dedupe Table Filters — Specify a path from a bucket to a prefix, and we would aim to grab just a single object from that prefix. This helps avoid scanning prefixes that may have partition tables with all the same schemas.
- Start each path with the bucket name and end it with
/. Separate paths with commas. For example,bucket-name/path/to/table/allows us to grab a single object from that prefix, even if multiple prefixes and objects are still available for scanning.
- Start each path with the bucket name and end it with
- File Extensions — Only scan objects that have the extensions specified here. This can also include files without extensions, by including the
*character in the field. To scan all files, leave the field empty.- The form sets default extensions:
parquetfor S3 Parquet, andjsonl, jsonfor S3 JSONL. You can edit them. Make sure that the file formats captured are of the expected type for the integration. If a scan captures a file that the integration does not support, the file can still be saved and displayed, but would not be available for classification.
- The form sets default extensions:
- File Regexes — Only scan objects that match the regex. This can be left empty if not needed.
- Scan One Object Per Prefix — The default is
truefor both integrations.
For Amazon S3, the connection form does not have these filters. Set them in the Unstructured Data Discovery plugin settings on the Scan Configuration tab instead. See Amazon S3 Plugins Configuration. The Amazon S3 integration sets no default file extensions and no file type limit.